New York Machine Learning Research Guild
An informal machine-learning research community in New York. Monthly colloquia, a Discord for trading ideas, and working on research together. Open to anyone with a sincere interest with the will to do Great Work.
Colloquia & Events
Come to learn about the latest in research, and to share about your whacky ideas. Of course, meeting the others, putting faces to names, and talking shop is part of the fun.
- Food and drinks are provided when available.
- Seats are limited by room capacity, so reserve one on Luma before you come.
- Signed up but can't make it? Cancel on Luma. It frees the seat for someone else and prevent food waste.
- Speaker
- Yair Schiff
- Affiliation
- PhD Candidate, Department of Computer Science, Cornell University
- Research
- Diffusion language models and generative modeling · with Volodymyr Kuleshov
- Partner
- Intuit
- Venue
- Intuit NYC · 51 Astor Pl, New York, NY 10003
Yair Schiff is a computer science PhD candidate at Cornell University, based at Cornell Tech in New York and advised by Volodymyr Kuleshov. Yair is currently a PhD intern at NVIDIA. Yair works on generative modeling, optimal transport, and AI for science, and recent work centers on diffusion language models, which generate text by iteratively unmasking tokens rather than writing left to right. This includes MDLM (NeurIPS 2024), a simple masked diffusion recipe for language modeling, guidance mechanisms for discrete diffusion (ICLR 2025), remasking for inference-time scaling, and an encoder-decoder design for faster training and inference (both NeurIPS 2025). Other work includes Caduceus (ICML 2024), a bidirectional, equivariant DNA language model, and DySLIM (ICML 2024) for learning stable models of chaotic systems. Before the PhD, Yair was a developer on IBM Watson Machine Learning, contributing to IBM Research's Trusted AI work and the winning entry of the 2020 VizWiz Grand Challenge. Yair has also been a student researcher at Google and a research intern at InstaDeep, and holds an MS in computer science from NYU Courant and a BA in economics from the University of Pennsylvania.
Speed, Guidance, and In-Place Editing with Diffusion Models for Text
Progress in diffusion models for discrete data has posed a useful alternative to the dominant autoregressive approach to language modeling. This new paradigm holds the promise of accelerated inference, more steerable generation, and higher quality outputs. In this talk we will discuss a prominent approach for diffusion language modeling, masked diffusion, and explain why it also poses a challenge to materializing the promised benefits of diffusion for text. We will then cover recent work for mitigating the issues of masked diffusion and different model parameterizations that can help realize the benefits of speed, control, and iterative refinement of diffusion language models.
- Speaker
- Rohun Agrawal
- Affiliation
- PhD Candidate, Department of Computer Science, Columbia University
- Research
- World-model planning and large-scale memory retrieval
- Speaker
- Leon Li
- Affiliation
- PhD Candidate, Tandon School of Engineering, New York University
- Research
- Self-improving AI, continual learning and post-training
- Partner
- Intuit
- Venue
- Intuit NYC · 51 Astor Pl, New York, NY 10003
Rohun Agrawal is a computer science PhD candidate at Columbia University, co-advised by Micah Goldblum and Pavel Izmailov, and an NSF Graduate Research Fellow. Rohun's research pushes the temporal horizons of machine learning models: extending the future horizon through planning with world models, and the past horizon through efficient large-scale memory retrieval. Recent work closes the train–test gap in world models for gradient-based planning, and earlier work on visual agentic AI for spatial reasoning with a dynamic API appeared at CVPR 2025. Rohun earned a BS in applied and computational mathematics at Caltech, working with Georgia Gkioxari on visual reasoning and in Katie Bouman's lab on imaging inverse problems, and has interned at Apple on large video model training and at NASA's Jet Propulsion Laboratory.
Leon Li is a second-year computer science PhD candidate at New York University, advised by Pavel Izmailov and Micah Goldblum, and a researcher at Modal. Leon studies how to build AI systems that learn, improve themselves, and operate safely in the real world, with interests spanning automated AI research, continual learning, post-training science, and the alignment of superintelligence. Recent work includes “End-to-End Context Compression at Scale” (2026), PersonalLLM (ICLR 2025) for tailoring LLMs to individual preferences, and “LLM Generated Persona is a Promise with a Catch” (NeurIPS 2025). Before the PhD, Leon earned a BS and MS in computer science at Columbia University, graduating magna cum laude.
Advances in Architectures for Long Context and Retrieval
Long-context inference is bottlenecked by the growing KV cache, in both memory and latency. However, existing KV cache compression methods either lose accuracy or must prefill the entire context before they can compress it. We introduce Latent Context Language Models (LCLMs), a family of encoder-decoder compressors trained end-to-end at scale that map long inputs to a short sequence of latent tokens before the decoder consumes them. LCLMs establish a new Pareto frontier in accuracy versus latency and memory over KV cache compression, while unlocking new capabilities such as agents that skim a compressed context and expand relevant segments on demand, and nearly lossless online compaction of the model’s own outputs during generation. For grounding language models in large document corpora, Retrieval-Augmented Generation (RAG) is the ubiquitous solution, yet it relies on a brittle lookup that can’t be trained end-to-end and slows generation by prefilling long contexts. We introduce Retrieval Layers, learnable sparse cross-attention layers that retrieve external text in latent space and Pareto-dominate RAG on accuracy versus latency.
- Speaker
- Xinhao Liu
- Affiliation
- PhD Candidate, Tandon School of Engineering, New York University
- Research
- Embodied AI and universal navigation · with Chen Feng (AI4CE Lab)
- Venue
- Manhattan, NY · venue TBA
Xinhao Liu is a computer science PhD candidate at NYU, advised by Chen Feng in the AI4CE Lab, and is currently at Amazon FAR (Frontier AI and Robotics). Xinhao's research aims at universal navigation: embodied agents that can go anywhere humans can go, drawing on world modeling, video understanding, and digital twins. CityWalker (CVPR 2025) learns urban navigation from web-scale walking videos, and Wanderland (CVPR 2026, highlight) builds geometrically grounded simulation for open-world embodied AI. Earlier work spans LiDAR mapping and 3D scene understanding, including DeepMapping2 (CVPR 2023) for self-supervised large-scale map optimization and Occ4cast and SSCBench (both IROS 2024) for occupancy forecasting and semantic scene completion. Xinhao interned at Waymo in summer 2025 and earned a BSc in honors mathematics and data science from NYU and NYU Shanghai.
Grounding Over Appearance: Scaling Embodied AI with the World's Own Geometry
Embodied AI increasingly bets on scale: larger models, more pixels, more text. Yet the failures that matter most for an agent acting in the world are physical: it trains in simulators that look right but are geometrically wrong, or walks past a goal it has already found. In this talk, I will show that what embodied learning needs to scale is not appearance but grounding, and that the world's own geometry, recoverable from observation, is what makes this possible. I will conclude by discussing how such grounding might be learned directly from real-world video.
- Speaker
- Keifer Lee
- Affiliation
- AI Scientist, Intuit
- Research
- Applied Decision Intelligence · perception and planning in multi-agent systems
- Venue
- Manhattan, NY · venue TBA
Keifer Lee is an AI Scientist on Intuit's Trust & Safety team in New York and a Member of Technical Research at the New York Machine Learning Research Guild (NY-MLR). Keifer comes to research as an applied practitioner, drawn to the parts that make systems tick: why they work and how to engineer them. That curiosity led to a focus on Applied Decision Intelligence: machine learning systems that make decisions under uncertainty and risk. Keifer sees it as one spectrum applied across domains and modalities, from high-risk decisions at scale in fraud and abuse, security and finance to perception and planning in multi-agent systems. Keifer started out building credit risk systems at MoneyLion that underwrote billions of dollars in transactions each year, then earned a Master of Science in Computer Engineering at New York University, working on robotic perception and planning in Chen Feng's AI4CE Lab and at Nokia Bell Labs before joining Intuit. That work includes SO-NeRF, on active view planning for neural radiance fields, and SAVMap (ICRA 2026), on large-scale visual mapping. On his own time, Keifer leads the guild's community research groups on various projects that tickles their interests at the frontier.
Lilliputian Problems: Designing Billion-Dollar Decision Systems under Uncertainty & Risk
Every day, frontier AI labs face millions of adversarial interactions, and large payment processors move billions of dollars. Say we’re tasked with designing an adversary detection system to protect users on our platform, or a good old underwriting system to validate each transaction. How then can we engineer such high-stakes systems in a principled way, when mistakes can cost millions in losses? These are all high-volume decision problems under risk and uncertainty — I call them Lilliputian Problems, trivial individually but a menace at scale. What makes them hard is rarely one thing, but a combination of what I call the Cruelty of Reality: from non-linear relations and delayed, censored, or partially observable outcomes, to non-stationarity, fat tails, extreme prevalence imbalance, and adversaries amongst others. In this talk, I will first formulate Lilliputian Problems as a class of decision problems and introduce varying degrees of cruelness to characterize their hardness, both theoretically and in practice. I will then present a taxonomy of their problem classes, a unifying overview of existing approaches, and a principled practitioner-focused framework for solving them, with an underwriting system as a running example. Finally, I will share lessons I’ve learned along the way from solving Lilliputian Problems of my own.
- Speaker
- Yuki Miura
- Affiliation
- Assistant Professor, Tandon School of Engineering, New York University
- Research
- AI-based climate and infrastructure risk modeling for adaptation decisions · CERA Lab
- Venue
- Venue TBA
Yuki Miura is an Assistant Professor at New York University's Tandon School of Engineering, in Mechanical and Aerospace Engineering and the Center for Urban Science and Progress. She leads the Climate, Energy, and Risk Analytics (CERA) Lab. The lab connects climate and infrastructure risk modeling with adaptation decisions: what to protect, where, when and at what cost. On the modeling side, it builds fast GIS-based simulations of storm-surge flooding under sea level rise and bounded probability models for storm surges. It has also studied the flood risk that coastal storms pose to the New York City subway (Transportation Research Part D, 2025). Machine learning plays a growing role. PREDISM (NeurIPS 2021 workshop) used CNN ensembles to model pre-disaster risk in at-risk communities. RoofNet is a global multimodal dataset for classifying roof materials with vision-language models, and another project uses multimodal large language models to evaluate earthquake damage from crowdsourced images and text. On the decision side, Yuki has built optimization frameworks that choose when and where to deploy seawalls, green infrastructure and insurance within a budget. The work centers on New York's coastline and draws on interviews with city stakeholders (Natural Hazards, 2021; Frontiers in Climate, 2021). She is especially interested in where AI methods actually improve these decisions, and in how to validate risk models under uncertainty, when the future they forecast has not happened yet. Yuki is a member of the New York City Panel on Climate Change and serves on the faculty advisory board of the Volatility and Risk Institute at New York University's Stern School of Business. Before joining the faculty, she spent three years at Morgan Stanley, first as a quantitative strategist and then in climate risk management. She holds a PhD, MPhil and MS in Civil Engineering and Engineering Mechanics from Columbia University, where she was a Mindlin Scholar, and a Bachelor of Engineering in System Design Engineering from Keio University.
Abstract TBA.
- Speaker
- Jingyan Shen
- Affiliation
- PhD Candidate, Courant Institute of Mathematical Sciences, New York University
- Research
- How reasoning emerges from pretraining to RL post-training · with Matus Telgarsky and Pavel Izmailov
- Speaker
- Leon Li
- Affiliation
- PhD Candidate, Tandon School of Engineering, New York University
- Research
- Self-improving AI, continual learning and post-training
- Venue
- Manhattan, NY · venue TBA
Jingyan Shen is a second-year computer science PhD candidate at New York University's Courant Institute, advised by Matus Telgarsky and Pavel Izmailov. She studies when and why reinforcement learning (RL) post-training improves reasoning in large language models, and how that reasoning takes shape from pretraining onward. Related interests include scalable verification, RL environments and continual self-improvement. Recent work includes “Understanding Reasoning from Pretraining to Post-Training” (NeurIPS 2026), the basis of this talk, and “When Reasoning Meets Its Laws” (NeurIPS 2026), a best paper nominee at the NeurIPS 2025 Efficient Reasoning workshop. Earlier papers cover data-efficient RL fine-tuning (NeurIPS 2025) and MiCRo, on personalized preference learning, which won an Outstanding Paper Award at EMNLP 2025. She has also worked on data attribution, including 2D-OOB (NeurIPS 2024) and TimeInf (ICLR 2025). In summer 2026, she was a research scientist intern at Microsoft Research in New York. Before the PhD, she was a machine learning engineer at Pinterest. She holds a dual master's degree from Tsinghua University and Columbia University and a bachelor's degree in statistics from Wuhan University.
Leon Li is a second-year computer science PhD candidate at New York University, advised by Pavel Izmailov and Micah Goldblum, and a researcher at Modal. Leon studies how to build AI systems that learn, improve themselves, and operate safely in the real world, with interests spanning automated AI research, continual learning, post-training science, and the alignment of superintelligence. Recent work includes “End-to-End Context Compression at Scale” (2026), PersonalLLM (ICLR 2025) for tailoring LLMs to individual preferences, and “LLM Generated Persona is a Promise with a Catch” (NeurIPS 2025). Before the PhD, Leon earned a BS and MS in computer science at Columbia University, graduating magna cum laude.
Understanding Reasoning from Pre-training to Post-training
Reinforcement learning (RL) has become central to improving large language models (LLMs) on complex reasoning tasks, yet RL post-training is largely studied in isolation from the pretraining that precedes it. As a result, two basic questions remain open: (1) how do pretraining choices (model size, data) shape the returns to RL compute, and (2) what does RL actually do to the model? These questions are difficult to study in the standard LLM setting: pretraining corpora are vast and uncontrolled, making it hard to attribute behaviors to pretraining versus RL, and systematic compute sweeps across both stages are prohibitively expensive. To address these challenges, we use chess as a controlled testbed for studying reasoning across the full pretraining-to-post-training pipeline. We follow the standard LLM training pipeline by pretraining language models from 5M to 1B parameters on human chess games, supervised fine-tuning on synthetic reasoning traces, and running RL on chess puzzles with verifiable rewards. Using this framework, we establish a scaling law connecting pretraining and RL: the post-RL performance at given RL compute level is well-predicted from the pretraining loss, and the slope of the RL reward curves improves approximately linearly with the pretraining tokens. Beyond scaling, we find that RL does not simply sharpen the SFT policy: on easy puzzles it amplifies correct moves the SFT policy already preferred, while on hard puzzles it surfaces correct moves that were nearly absent under SFT. We further test whether our findings generalize beyond chess by training a 1B language model on math domain, where the same predictive pattern emerges: longer-pretrained checkpoints reach higher post-RL performance and improve faster under RL. In sum, we provide a quantitative account of the pretraining-to-RL interface and a controlled testbed for studying the science of reasoning across the full pretraining-to-post-training pipeline.
Past Sessions
- Speaker
- Arthur Jacot
- Affiliation
- Assistant Professor, Courant Institute of Mathematical Sciences, New York University
- Research
- Mathematical theory of deep learning
- Partner
- Intuit
- Venue
- Intuit NYC · 51 Astor Pl, New York, NY 10003
Arthur Jacot is an Assistant Professor at NYU's Courant Institute of Mathematical Sciences. Arthur builds mathematical theory for how deep neural networks learn, and is best known for introducing the Neural Tangent Kernel during a PhD at EPFL with Clément Hongler. Recent work explains how DNNs act as a computational Occam's razor, finding simple, low-dimensional representations when trained with weight decay. This includes a proof that wide networks trained with weight decay exhibit neural collapse (ICLR 2025, oral) and an account of how DNNs break the curse of dimensionality through compositionality and symmetry learning (ICLR 2025). The newest paper frames deep learning as a convex paradigm of computation that minimizes circuit size with ResNets. Arthur's honors include the 2025 AMR Prize in Mathematics of Artificial Intelligence and the 2023 EPFL PhD Thesis Prize.
Deep Learning as a Convex Paradigm of Computation: Minimizing Circuit Size with ResNets
The general intelligence properties of deep neural networks (DNNs) could stem from their ability to implement a computational Occam's razor: searching over data-fitting programs to select the simplest one. However, minimizing algorithmic complexity is notoriously difficult; how could a local search algorithm such as gradient descent recover the optimal program? For example, there currently exists no algorithm for the Minimum Circuit Size Problem (MCSP) that improves upon brute-force search. I recently discovered a regime of computation, the Harder than Monte Carlo (HTMC) regime, where circuit size becomes convex, allowing the definition of a norm whose minimization is equivalent to the MCSP. We then propose a greedy algorithm that builds a mixture of circuits, searching first over simple circuits before larger ones. On the other hand, large DNNs appear to operate exactly in the HTMC regime, and there is evidence that they might be implementing a similar circuit search algorithm.
- Speaker
- Zayne Sprague
- Affiliation
- PhD Candidate, Courant Institute of Mathematical Sciences, New York University
- Research
- Reasoning in language models · with Greg Durrett (TAUR Lab)
- Partner
- CUNY Tech Prep
- Venue
- Amazon JFK27 (Hank) · 12 W 39th St, New York, NY 10018
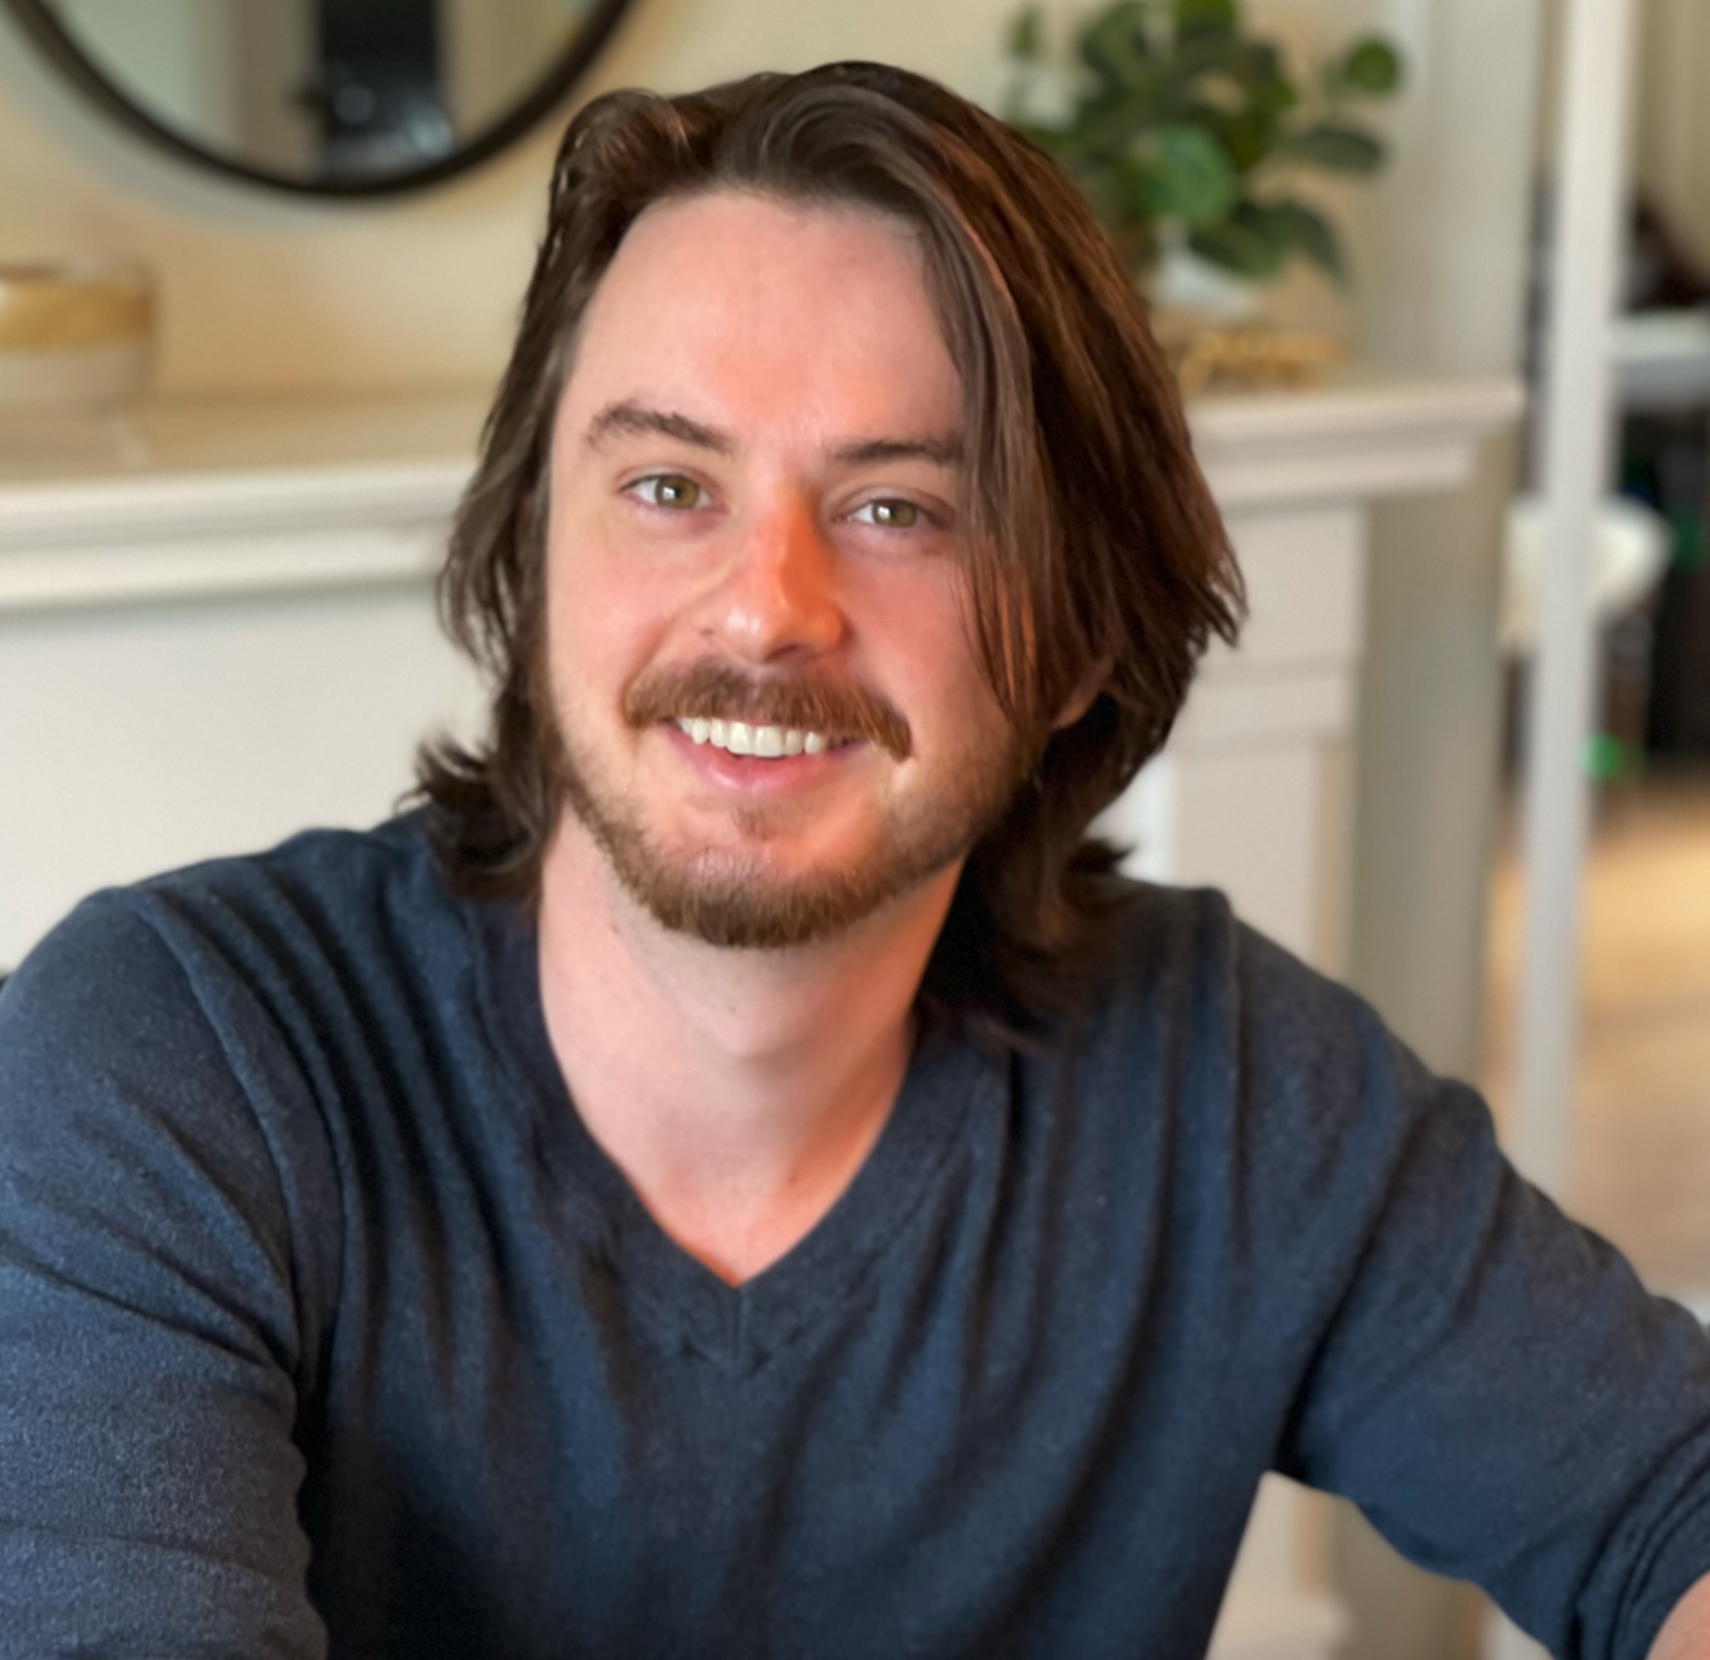
Zayne Sprague is an NLP PhD candidate at NYU's Courant Institute, advised by Greg Durrett in the TAUR Lab. Zayne's research asks how to evaluate reasoning in language models and how to instill it. MuSR (ICLR 2024 spotlight) introduced a benchmark of multistep soft-reasoning problems, and “To CoT or not to CoT?” (ICLR 2025) showed that chain-of-thought helps mainly on math and symbolic tasks. The latest work, SkillFactory (ICLR 2026), uses self-distillation to teach models reusable cognitive behaviors, alongside contributions to OpenThoughts (ICLR 2026, oral), a set of open data recipes for reasoning models. Before the PhD, Zayne earned a BA and MSc in computer science at UT Austin and spent seven years in industry, most recently as a senior software engineer at CoPilot. This summer, Zayne started an internship at Google.
From Chain of Thought to Agent Swarms: A Brief Story on Reasoning in LLMs
Giving language models more time to think has produced substantial gains, but in targeted domains, and the benefits appear to remain uneven across tasks. This talk explores how models can use additional computation at inference time effectively, reviewing the progression from prompt based methods to multi-agent systems. We will begin with chain-of-thought prompting, asking a model to think before giving a final answer, presenting our work showing that chain-of-thought prompting has its strongest benefits concentrated in mathematics and symbolic reasoning. These domains also share a practical advantage: answers can often be checked automatically, providing feedback that can be used to train models through reinforcement learning. This leads us to SkillFactory, where we use a model's own successful and unsuccessful attempts to construct training examples that demonstrate checking answers and retrying. Combining supervised finetuning on these examples with reinforcement learning helps models develop these behaviors and generalize to harder problems. Finally, we will discuss recent work on agent swarms, exploring how reasoning can scale in parallel and what role verification can play in making that additional computation useful.
What this is
Activities, functions and scope of the Guild
- Discord
- A shared space to trade knowledge, papers, and questions. Joining takes a short application through the invite link, which keeps out spam and bots.
- Monthly colloquia
- Researchers from local institutions and labs present their work; members meet, network, and exchange ideas. Open to attend, limited only by room capacity.
- Industry & events
- Sharing sessions with industry, hackathons, guild trips to conferences, and joint workshops.
- Working groups
- Small teams that take one research project from question to published result. See the open projects and how to join.
Culture & values
Our core guiding principles
Sincere interest is enough to belong.
Anyone genuinely curious about the field and its ideas has a place here.
Collaboration comes first.
Courtesy and respect are the baseline. Treat others as you'd want to be treated.
We aim high.
Welcoming as it is, the guild means to do work that matters.
The bar is there to lift, not to shut people out.
Standards exist to push everyone toward better work, not to gatekeep for its own sake.
Give back what you were given.
Help others grow, and yield when it's called for. That's what a community is for.
“If you don't work on important problems, it's not likely that you'll do important work.”— Richard Hamming